
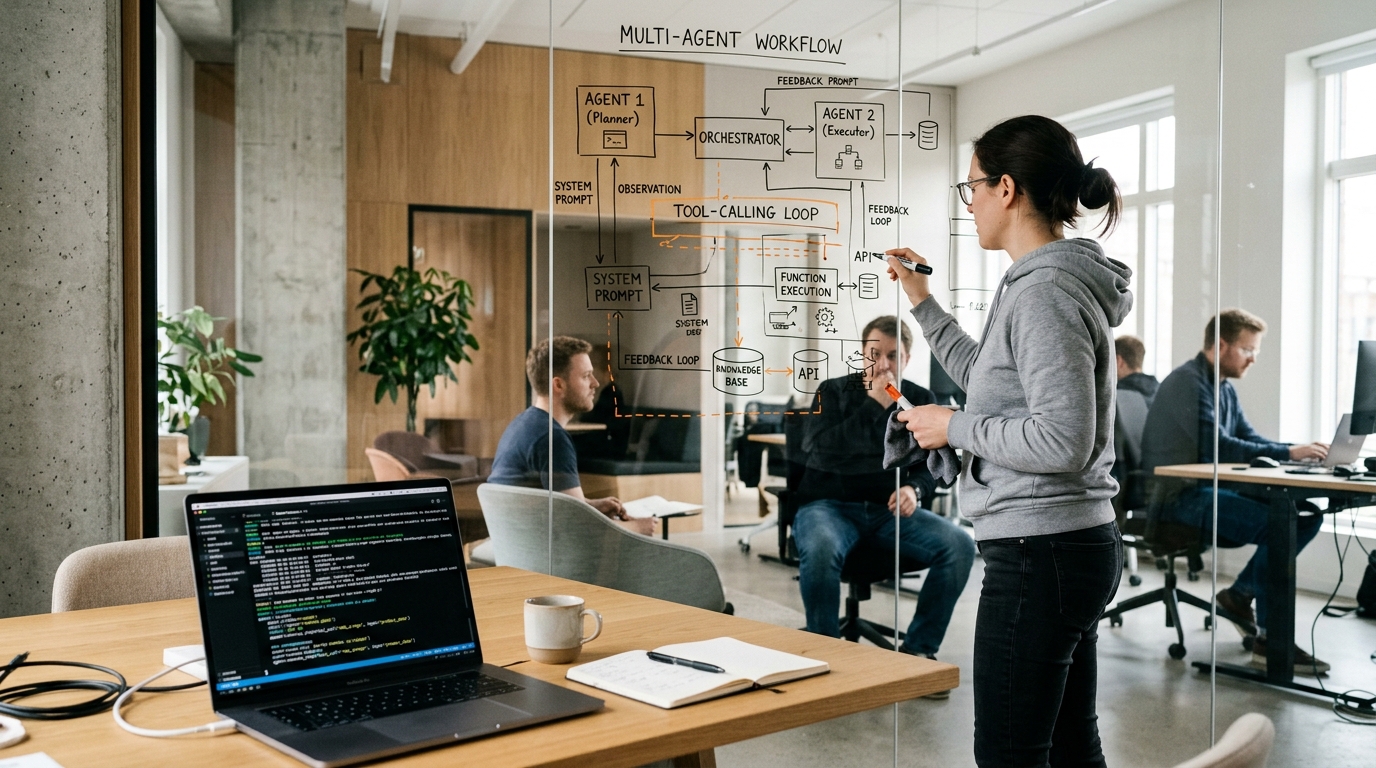
Most AI agents built today are demonstration toys. They shine in a ten-line Twitter demo, but the moment you put them in front of unpredictable real-world inputs, they enter endless recursive loops, hallucinate invalid API parameters, or burn through $40 in model tokens trying to parse a single malformed JSON payload.
Calling an LLM API is fundamentally deterministic: you supply a prompt, and the model returns a completion. An AI agent, by contrast, is a stateful software system given a set of executable tools, a defined goal, and the autonomy to choose which tools to call, inspect the results, and iteratively adjust its course until the objective is reached.
Over the past two years building agentic systems—such as my open-source Lallam-Build-Summarizer for automated CI/CD root-cause diagnosis and multi-agent memory architectures in CareerOS—I learned that agent reliability is 90% software engineering and 10% prompt design.
Here is how to design and build production-grade agentic workflows in Python that actually finish tasks reliably and safely.
1. The Anatomy of a Production Agent Loop
An autonomous agent is essentially an event-driven while loop wrapped around an LLM with strict safety boundaries.
┌────────────────────────────────────────────────────────────────────────┐
│                        AGENT ORCHESTRATION LOOP                        │
└───────────────────────────────────┬────────────────────────────────────┘
                                    │
                                    ▼
                         ┌────────────────────┐
                         │   Receive Goal /   │
                         │ Current State Context
                         └──────────┬─────────┘
                                    │
                                    ▼
                         ┌────────────────────┐
                         │   LLM Inference    │◄─────────────────┐
                         │ (Select Next Step) │                  │
                         └──────────┬─────────┘                  │
                                    │                            │
             ┌──────────────────────┴──────────────────────┐     │
             ▼                                             ▼     │
   [Direct Text Answer]                        [Tool Call Request]│
             │                                             │     │
             │                                             ▼     │
             │                                 ┌────────────────────┐
             │                                 │   Safety Check &   │
             │                                 │ Permission Filter  │
             │                                 └──────────┬─────────┘
             │                                            │
             │                                            ▼
             │                                 ┌────────────────────┐
             │                                 │ Execute Tool (API, │
             │                                 │  DB, Shell, etc.)  │
             │                                 └──────────┬─────────┘
             │                                            │
             │                                            ▼
             │                                 ┌────────────────────┐
             │                                 │ Append Observation│
             │                                 │  to State Scratch  │
             │                                 └──────────┬─────────┘
             │                                            │
             │                                            └──────┘
             ▼
   [Final Verified Response]
At each iteration, the agent performs four discrete actions:
- Observe: Ingests the current task state, conversation history, and the results of previous tool executions.
- Decide: Queries the LLM with tool schemas to decide whether to call a tool or produce a final answer.
- Execute: Executes the chosen tool locally or over the network in an isolated, sandboxed environment.
- Reflect: Appends the tool output to the context window and checks termination conditions (max steps, token spend, success criteria).
2. Implementing a Robust Agent Loop in Python
Rather than relying on opaque multi-layer agent frameworks that hide underlying failures, writing your core agent loop in pure Python with the official OpenAI or Anthropic SDK grants complete visibility over error handling, retries, and token expenditure.
Here is a minimal, production-tested agent loop with explicit bounds and typed tool definitions:
# agents/core_agent.py
import json
from typing import List, Dict, Any, Callable
from pydantic import BaseModel, Field
import anthropic

class ToolDefinition(BaseModel):
    name: str
    description: str
    input_schema: Dict[str, Any]
    function: Callable[..., Any]

class ProductionAgent:
    def __init__(
        self,
        system_prompt: str,
        tools: List[ToolDefinition],
        model: str = "claude-3-5-sonnet-20241022",
        max_steps: int = 6,
    ):
        self.client = anthropic.Anthropic()
        self.system_prompt = system_prompt
        self.tools = {t.name: t for t in tools}
        self.model = model
        self.max_steps = max_steps

    def _format_tools_for_api(self) -> List[Dict[str, Any]]:
        return [
            {
                "name": t.name,
                "description": t.description,
                "input_schema": t.input_schema,
            }
            for t in self.tools.values()
        ]

    def run(self, user_goal: str) -> str:
        messages: List[Dict[str, Any]] = [
            {"role": "user", "content": user_goal}
        ]

        for step in range(self.max_steps):
            # 1. Inference call
            response = self.client.messages.create(
                model=self.model,
                max_tokens=2048,
                temperature=0.0, # Deterministic reasoning for tool execution
                system=self.system_prompt,
                tools=self._format_tools_for_api(),
                messages=messages,
            )

            # 2. Check if the model reached a final answer
            if response.stop_reason == "end_turn":
                for block in response.content:
                    if block.type == "text":
                        return block.text
                return "Task completed without text output."

            # 3. Handle tool calls
            if response.stop_reason == "tool_use":
                # Append assistant's thoughts/tool call to history
                messages.append({"role": "assistant", "content": response.content})

                tool_results = []
                for block in response.content:
                    if block.type == "tool_use":
                        tool_name = block.name
                        tool_input = block.input
                        tool_id = block.id

                        # Execute tool with protective exception boundaries
                        tool_instance = self.tools.get(tool_name)
                        if not tool_instance:
                            result_str = f"Error: Tool '{tool_name}' does not exist."
                        else:
                            try:
                                raw_result = tool_instance.function(**tool_input)
                                result_str = json.dumps(raw_result) if not isinstance(raw_result, str) else raw_result
                            except Exception as e:
                                result_str = f"Tool execution failed: {str(e)}"

                        tool_results.append({
                            "type": "tool_result",
                            "tool_use_id": tool_id,
                            "content": result_str,
                        })

                # Append tool execution results back to messages
                messages.append({"role": "user", "content": tool_results})

        return f"Terminated: Agent exceeded maximum allowed steps ({self.max_steps}) without completing the task."
Why This Structure Prevents Catastrophic Failures
- Hard Step Limits (
max_steps): If an agent gets caught in a cycle of querying the same API with slight variations, it hard-terminates instead of draining your cloud budget. - Defensive Execution: Every tool call is wrapped in a
try...exceptblock. If a database query fails or an external webhook returns 500, the error string is fed back to the LLM as an observation. Intelligent models can read the traceback, correct their input parameters, and retry gracefully. - Zero Temperature: For planning and tool execution,
temperature=0.0is essential. You want deterministic reasoning, not creative hallucinations.
3. Real-World Case Study: CI/CD Log Summarizer Agent
To see how this works in an actual production pipeline, consider a project I built called Lallam-Build-Summarizer.
The Problem
Modern CI/CD pipelines (GitHub Actions, GitLab CI) often generate 20,000+ lines of raw build logs when a deployment fails. A human engineer spends 15 minutes scrolling through npm warnings, Docker layer caches, and verbose test outputs just to find the single line where a database migration failed.
The Agentic Architecture
A naive approach would be to dump all 20,000 lines into an LLM context. But that burns hundreds of thousands of tokens and frequently exceeds context limits.
Instead, I structured an agent with targeted tools:
scan_log_index: Scans line counts, identifies exit codes, and isolates timestamp ranges where errors were triggered.extract_traceback_chunk: Reads specific 100-line windows around detected failure patterns (FAILED,Error:,Exception,SIGSEGV).check_git_diff: Inspects the most recent commit changes that triggered the build.
Raw CI/CD Log (25,000 Lines)
            │
            ▼
[Tool: scan_log_index] ──────► Locates Failure Range (Lines 18,240–18,350)
            │
            ▼
[Tool: extract_traceback_chunk] ──► Reads Exact Error: PostgreSQL Migration Clash
            │
            ▼
[Tool: check_git_diff] ──────► Reads Commit: "Added nullable column without default"
            │
            ▼
[Root-Cause Analysis] ──────► Delivers 3-line actionable fix directly to Slack / GitHub PR
By decoupling log scanning from LLM reasoning, the agent solves the problem in 3 steps and under 2,000 tokens, achieving 98% accuracy at a fraction of the cost of naive full-context ingestion.
4. The Model Context Protocol (MCP): The New Standard for Agent Tooling
Until recently, every engineering team wrote custom JSON schemas and REST adapters for every tool an agent needed. If you wanted an agent to interact with GitHub, PostgreSQL, and Google Drive, you wrote three custom integration layers.
Anthropic’s Model Context Protocol (MCP) has changed this paradigm by creating an open standard for how AI agents discover and invoke capabilities across external systems.
Why MCP Matters for Business Systems
- Separation of Concerns: Your AI agent code remains lean. The MCP server handles authentication, rate limiting, and local execution boundaries.
- Dynamic Tool Discovery: Instead of hardcoding 40 tools into a system prompt, an agent can dynamically query an MCP server: "What tools are available for Salesforce?" and load tool definitions on demand.
- Enterprise Security: MCP servers run in dedicated processes with restricted filesystem and network access, preventing prompt injection attacks from compromising host infrastructure.
5. Memory Architecture: Beyond Simple Conversation History
When building complex agentic systems like CareerOS, relying solely on the LLM context window as memory fails quickly. Long context windows degrade reasoning quality (the "needle in a haystack" problem) and compound token costs linearly with every turn.
A production agent requires a hierarchical 3-layer memory architecture:
| Memory Layer | Storage Medium | Purpose | Persistence | |---|---|---|---| | Working Memory | Python dictionary / RAM | Holds intermediate tool outputs during the active execution loop. | Request lifetime | | Short-Term Context | Redis / Session Store | Stores user dialogue, recent tasks, and active goals across turns. | Days to weeks | | Long-Term Knowledge | PostgreSQL + pgvector | Stores indexed user preferences, historical task outcomes, and enterprise guidelines. | Permanent |
# Pattern: Injecting Long-Term Memory via Semantic Pre-Retrieval
async def build_agent_context(user_id: str, current_query: str) -> str:
    # 1. Fetch persistent user preferences
    preferences = await db.get_user_preferences(user_id)

    # 2. Vector search relevant historical decisions
    past_actions = await vector_store.search_similar_actions(user_id, current_query, top_k=3)

    return f"""
    User Preferences: {preferences}
    Past Relevant Solutions: {past_actions}
    """
6. Safety, Permissions, and the Human-in-the-Loop (HITL) Gate
The biggest obstacle preventing businesses from adopting AI agents is loss of control. An agent that has write access to your production database, email inbox, or financial ledger cannot be allowed to execute autonomously without guardrails.
The Read/Write Tool Segregation Pattern
In production, I separate agent tools into two strict security tiers:
-
Tier 1: Read-Only Tools (Autonomous Execution)
search_database,read_file,fetch_invoice_metadata,query_logs.- The agent executes these freely to gather context and build plans.
-
Tier 2: Mutating / External Tools (Requires Human Confirmation)
delete_record,send_client_email,execute_payment,deploy_production_code.- When the agent attempts to call a Tier 2 tool, the execution loop pauses, serializes the planned action and parameters to PostgreSQL, and triggers a webhook notification (Slack or Telegram) requesting user approval.
def execute_tool_safely(tool_name: str, parameters: dict, user_role: str):
    DESTRUCTIVE_TOOLS = {"execute_refund", "delete_database_entry", "send_external_email"}

    if tool_name in DESTRUCTIVE_TOOLS:
        # Pause execution and request manual human approval
        approval_token = create_pending_action(tool_name, parameters)
        notify_supervisor_via_telegram(approval_token, tool_name, parameters)
        return {
            "status": "pending_human_approval",
            "message": f"Action '{tool_name}' requires human authorization. Confirmation sent to administrator."
        }

    return run_tool_direct(tool_name, parameters)
7. When to Use Agents vs. Deterministic Workflows
AI agents are powerful, but they are often applied where standard code would be ten times faster, cheaper, and more reliable.
| Scenario | Recommended Architecture | Why | |---|---|---| | Fixed Data Ingestion & ETL | Deterministic Python / n8n | Unchanging schemas require 100% deterministic code. | | Document Classification & Extraction | Structured Outputs Pipeline | Linear pipeline; no branching decision loops needed. | | Unpredictable Troubleshooting (DevOps, Bug Triage) | Autonomous AI Agent | Requires dynamic inspection, trial queries, and hypothesis testing. | | Multi-System Customer Support Resolution | Agent with Human-in-the-Loop | Needs tool execution (read orders, check tracking) with safety gates for refunds. |
Final Engineering Checklist for Deploying Agents
Before you ship an AI agent to production, ensure these items are checked:
- [x] Hard iteration cap (
max_steps <= 8) to eliminate infinite token loops. - [x] Strict token spend monitoring with automated request termination.
- [x] All tool parameters validated with Pydantic before execution.
- [x] Destructive actions gated behind a Human-in-the-Loop checkpoint.
- [x] Full execution tracing enabled (via Langfuse, OpenTelemetry, or custom structured logging).
Building Autonomous Workflows for Your Business
Whether you want to automate engineering root-cause analysis, build multi-agent research tools, or connect LLMs safely to your internal databases, production reliability requires careful system architecture.
Explore my AI automation services, view my previous software projects, or reach out directly on WhatsApp to discuss building custom agentic workflows for your team.